EPISODE 08
The Lock Comes Off
AI Coronation & the Speed Reckoning · 2015–now
AI's money meets a thirty-year-old lock. Two funded teams attack speed and the GIL — and the ecosystem the lock accidentally created pays to remove it. Full circle.
November 2020.
Guido van Rossum, retired for a year, tweets that retirement was boring — he's joined Microsoft, and he has a plan about performance.
The World
First, the coronation.
In November 2015, Google releases TensorFlow, and it speaks Python. Not because anyone at the core of the language lobbied for it — because episode 4 had already happened. The numpy idioms were the lingua franca of numerical code. The notebooks were on every researcher’s laptop. The grad students were already trained. When the biggest company in search needed a frontend for its machine-learning framework, the decision made itself: the audience was standing there, holding Python.
PyTorch arrives in 2017, and it carries a lesson in its luggage. It’s ported from Lua Torch, and Lua — by most accounts — had the better runtime story. Faster, lighter, cleaner to embed. It lost anyway. It lost on ecosystem, which is the only axis this series has ever really been about. If you want a one-sentence summary of episodes 1 through 8, it’s the Torch port: the runtime doesn’t pick the winner; the shelves full of libraries do.
Then the dominoes go quickly. Keras. Hugging Face’s transformers library, 2018–19. And in November 2022, ChatGPT — the moment the AI boom stops being an industry story and becomes a civilizational one. Underneath all of it, the same architecture: Python glue over CUDA. Thin orchestration on top, screaming-fast GPU kernels below the line. You’ve seen this diagram before. It’s the Accidental Gift from episode 4, with the C blocks relabeled.
Then, the bill.
Cloud economics did something no benchmark war ever managed: it turned “Python is slow” from a forum argument into a line item. When your code runs on one laptop, interpreter overhead is a shrug. When it runs on an Instagram- or Dropbox-scale fleet, every wasted cycle is multiplied by a hundred thousand machines and printed on an invoice. Someone in finance can now see the interpreter. That changes everything.
The Pressure
Two vectors converge on the core at once, and for the first time in this whole story, they point at the same place.
Vector one: AI workloads want threads. Training and serving pipelines have to keep GPUs fed — data loaders pulling and transforming batches, serving layers juggling requests — and the natural tool for “do several things at once inside one process, sharing memory” is threading. Which is exactly the tool the GIL has quietly hobbled since 1992. The old workaround, multiprocessing, means separate processes that can’t share objects without serializing them across a boundary — a tax you pay per batch, forever. The lock that was a footnote in 1992 and a villain in 2010 is now standing between the industry’s most expensive hardware and its lunch.
Vector two: fleet cost wants a faster interpreter. Not a research project, not “just use PyPy” — a faster CPython, the one production actually runs.
Here is what’s new. In every previous episode, the motivation to fix Python’s speed existed but the money didn’t, or the money existed but pointed elsewhere. Now the money and the motivation both point at the core. That has never happened before. Watch what happens when it does.
The Response
A war on two fronts.
Front one: make it faster. “I have a plan to speed up CPython by a factor of five over the next few years. But it needs funding.” That was Mark Shannon on python-dev, October 20, 2020 — a public plan with a public price tag, which is not how core Python development had ever worked. Microsoft provided it, funding the Faster CPython team from 2021: Guido, Shannon, Brandt Bucher, and colleagues. Salaried engineers, working full-time, on making the interpreter itself faster.
The results shipped on cadence. 3.11 brought the specializing adaptive interpreter (PEP 659) — officially “an average of 25% faster than 3.10” — plus zero-cost exceptions. The idea behind specialization is worth a minute, because it explains where a quarter of your runtime just went. A generic bytecode instruction like a binary add has to ask, every single time: are these integers? floats? strings? something with a dunder method? The adaptive interpreter watches your code run, notices that this particular addition has seen integers five thousand times in a row, and quietly rewrites the instruction into a specialized version that assumes integers and just adds them — keeping a cheap guard that falls back to the generic path if a string ever shows up. Your code doesn’t change. The interpreter learns it.
3.12 added comprehension inlining (PEP 709) and a per-interpreter GIL (PEP 684) — the payoff of Eric Snow’s decade-long campaign to make subinterpreters real, meaning one process can now hold multiple isolated interpreters, each with its own lock. 3.13 shipped a copy-and-patch JIT compiler (PEP 744) — experimental, off by default, a foundation being poured rather than a speedup being promised. 3.14 brought a tail-call interpreter and put subinterpreters in the standard library (PEP 734, as concurrent.interpreters).
A sober note belongs here, because a documentary owes you the whole arc: in May 2025, Microsoft canceled its support for the project and most of the team was laid off days before PyCon. The speed work continues — but the funding question, the one Shannon’s very first message raised, has reopened.
Front two: remove the lock. Recite the lineage, because this is the fourth attempt. Greg Stein, 1996: fine-grained locks, single-threaded performance craters, Guido sets the bar — no single-threaded regression. The Gilectomy, 2016–17: Larry Hastings’ attempt, dead on the same cliff. Then, October 7, 2021: Sam Gross posts nogil to python-dev.
What makes nogil different is that it attacks the actual problem. The GIL exists because reference counting — Python’s way of knowing when to free an object — isn’t thread-safe: two threads bumping the same counter without coordination will corrupt it. The naive fix, making every count atomic, is what killed the earlier attempts; atomic operations are expensive, and Python touches refcounts constantly. Gross’s design spends its cleverness on not paying that cost. Biased reference counting gives each object a fast, uncoordinated counter for the thread that owns it — the common case — and a slower, synchronized counter for everyone else. Immortal objects take the things every thread touches constantly — None, True, small integers — and freeze their refcounts entirely, so there’s nothing to fight over. Deferred reference counting skips the bookkeeping for objects like functions and modules that live on every call stack, letting the garbage collector settle the score later. Add mimalloc for thread-safe allocation, and you get the first GIL removal in a quarter century that doesn’t tank single-threaded speed. The bar Guido set in the nineties is finally cleared.
What happens next is episode 7’s machinery working as designed. No BDFL rules by decree; the community deliberates in the open, in enormous threads on discuss.python.org. Mid-debate, Meta puts money on the table — a pledge of three engineer-years, conditional on acceptance. Then the Steering Council announces its intent to accept PEP 703 in July 2023, and formalizes the acceptance that October 24 — with a phased, explicitly reversible plan, because this community has a scar named episode 5 and refuses to break the world again. 3.13 ships the experimental free-threaded build. PEP 779 makes free-threading officially supported in 3.14, October 2025.
Now say the full-circle beat out loud, because it is the whole series in four moves. The GIL pushed compute into C — that was episode 1, the lock that made pure-Python threading useless for heavy work and drove the heavy work below the line. The C ecosystem won science — that was episode 4, MATLAB refugees and NumPy and the accidental gift. Science became AI — that was this episode’s first act, TensorFlow and PyTorch choosing Python because the scientists were already there. And AI’s owners paid to remove the GIL. The flaw built the ecosystem; the ecosystem became an industry; the industry funded the fix for the flaw. Thirty-four years, one loop, closed.
Epilogue. The pressure never stops; it just changes language. Look below the line today and the new arrivals aren’t written in C — ruff, uv, polars, pydantic-core, all riding PyO3. The Rust wave is “the new C”: once again, the fast layer accretes underneath a Python surface, and once again nobody planned it. Meanwhile CPython keeps answering pressures as they arrive — official iOS and Android tiers in 3.13, t-strings (PEP 750) in 3.14. Language features are lagging indicators of industry pressure. They always were. Roll credits.
The Fight
- From:
- Sam Gross
- Date:
- October 7, 2021
- Subject:
- Python multithreading without the GIL — python-dev
- From:
- Thomas Wouters (for the Steering Council)
- Date:
- July 28, 2023
- Subject:
- A Steering Council notice about PEP 703
“We intend to accept PEP 703.”
- From:
- The Steering Council
- Date:
- October 24, 2023
- Subject:
- PEP 703 acceptance, with rollout provisos
The community’s deepest fear surfaced by name: will there be two Pythons again? It wasn’t paranoia — it was arithmetic. A free-threaded interpreter has a different ABI, which means every compiled extension has to be built for it separately: the cp313t builds, distinct wheels for the same package on the same Python version. Squint and it looks like the opening frames of episode 5 — an ecosystem split down the middle, libraries waiting for users, users waiting for libraries. The abi and wheel debates were argued explicitly in that shadow, which is precisely why the acceptance came wrapped in phases and an escape hatch.
- From:
- Thomas Wouters (for the Steering Council)
- Date:
- July 28, 2023
- Subject:
- The SC on the split risk, in the PEP 703 notice
“We do not want another Python 3 situation. … We do not want to create a permanent split between with-GIL and no-GIL builds (and extension modules).”
And the two funded fronts tugged against each other, because their tricks collide. Specialization works by rewriting bytecode in place based on what one thread has observed — cheap and safe when a lock guarantees only one thread runs at a time. Remove the lock, and those adaptive rewrites become shared mutable state: two threads racing through the same function can disagree about what the instruction underneath them currently is. Every optimization the Faster CPython team built on single-threaded assumptions has to be re-derived for a world without them. The tension threads between the two teams are their own genre.
- From:
- Mark Shannon (Faster CPython lead)
- Date:
- June 2, 2023
- Subject:
- PEP 703 (3.12 updates) — the two fronts collide
“The adaptive specializing interpreter relies on the GIL; it is not thread-friendly. If NoGIL is accepted, then some redesign of our optimization strategy will be necessary.”
Why Your Code Looks Like This
Why does python3.13t exist — a second binary, one trailing letter of difference? Because free-threading shipped as a separate build, not a flag, so nobody’s production broke by surprise. Why do some wheels ship two builds of the same version? Same reason: a free-threaded interpreter needs extensions compiled for it, so the ecosystem carries both while the transition runs. Why do your NumPy and PyTorch upgrade notes suddenly mention free-threading? Because the libraries below the line — the ones the GIL protected for thirty years — now have to declare, one by one, that they’re safe without it.
And why is “is the GIL gone?” no longer a yes/no question but a version question — which Python, which build, which year? Because that’s what removing a thirty-four-year-old load-bearing lock actually looks like: not a switch flipped, but a slow, phased, reversible handover, argued in public, funded by the industry the lock accidentally built. After thirty-four years, that is what victory looks like.
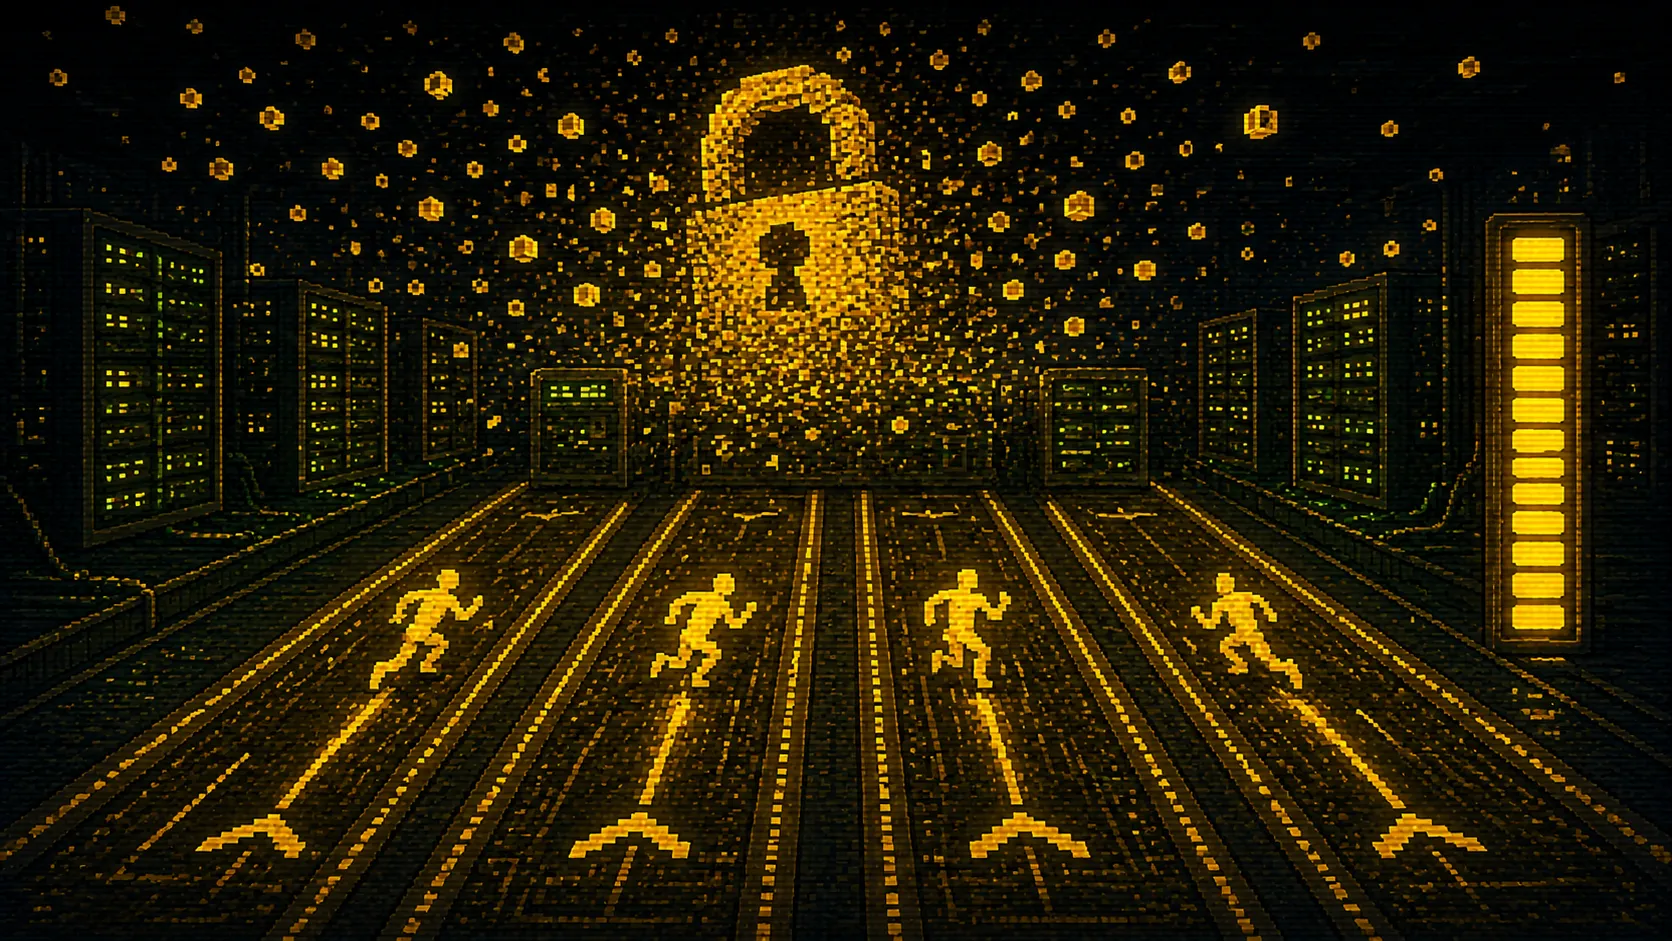
1991: one core. The lock passes around — 100% utilization. The GIL was the right call.
2006: the free lunch ends. The same lock dance on four cores — utilization collapses to 25%.
2024+: the padlock dissolves — four lanes light simultaneously, the meter climbs to 100%. The GIL pushed compute into C → the C ecosystem won science → science became AI → AI's owners paid to remove the GIL.
A metaphor, not a scheduler simulation.
[ AWAITING DATA — numbers must be cited, not remembered ]
No official cumulative 3.10→3.14 series exists. Citable per-release claims:
3.11 averages 25% faster than 3.10 (python.org What’s New); 3.12 and 3.13
publish no overall figure; 3.14’s tail-call interpreter adds a 3–5%
geometric mean on pyperformance against its own baseline.
Sources
- Mark Shannon’s plan.md — 5x in four stages
- Shannon’s “Speeding up CPython” post, python-dev (October 20, 2020)
- PEP 659 — Specializing Adaptive Interpreter · PEP 709 · PEP 684 · PEP 744 · PEP 734
- PEP 703 — Making the GIL Optional in CPython · PEP 779 — supported free-threading
- Sam Gross’s nogil announcement (October 7, 2021)
- SC intent-to-accept (July 2023) · formal acceptance (October 2023)
- Meta’s engineer-years pledge (July 2023)
- Community stewardship of Faster CPython — the May 2025 layoffs · LWN coverage
- Larry Hastings, “Removing Python’s GIL: The Gilectomy” (PyCon 2016)
- What’s New in Python 3.11 · 3.14
- PEP 750 — Template Strings · PEP 730 — iOS · PEP 738 — Android